Why the Same Text Produces Different Hex Values
Discover why identical text can produce different hex values across systems and learn how character encoding, Unicode, and hidden characters affect the result.
- The Text Looks Identical, but Is It Really the Same?
- Three Reasons Your Hex Output Doesn't Match
- 1. Different Character Encodings
- 2. Hidden Characters That Sneak Into the Text
- 3. Unicode Normalization and Different Text Representations
- Run a Small Experiment Before You Debug Anything
- How to Find Where the Difference Starts
- When Should You Use a Text-to-Hex Converter?
- A Quick Checklist Before You Blame the Data
You copy a short piece of text, convert it to hexadecimal, and get one result. Then you run what looks like the exact same text through another application, script, or API—and suddenly, the hex output is different. Did something corrupt your data? Did one system change the characters? Or is hexadecimal doing something more complicated than it first appears?
Before blaming the software, take a closer look at what you're comparing. Two strings can look identical on screen without having exactly the same underlying bytes. That's the key to understanding why seemingly identical text can produce different hexadecimal values.
The Text Looks Identical, but Is It Really the Same?
Hexadecimal is a way to represent numerical values using sixteen symbols: 0–9 and A–F. When you convert text to hex, the result usually represents the bytes produced by encoding the text. Those bytes depend on the characters involved and the encoding used to represent them.
Consider the word Hello. Under UTF-8, its hexadecimal representation is:
48 65 6C 6C 6F
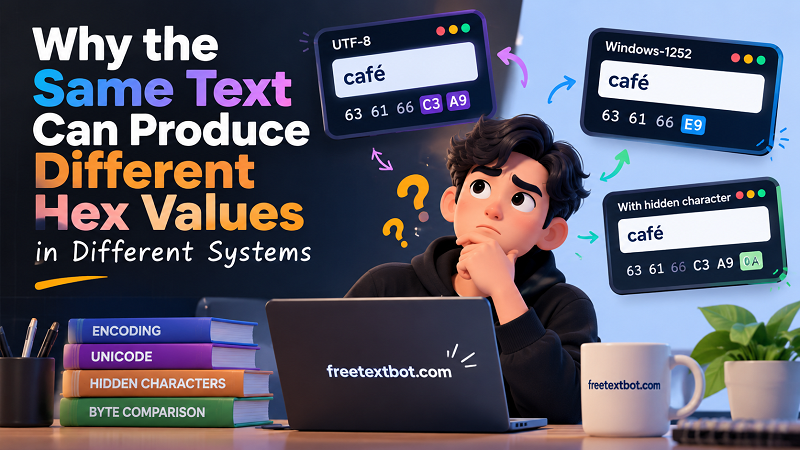
Every character in this example belongs to basic ASCII, so UTF-8 represents each one with a single byte. Now consider a word containing accented characters, such as café. Its UTF-8 representation is:
63 61 66 C3 A9
The final character, é, uses two bytes in UTF-8. If another system uses a different character encoding, that same visible word may produce a different byte sequence. The text hasn't necessarily changed; the rules used to represent it have.
There's another wrinkle: Unicode sometimes allows visually identical text to be represented by different sequences of code points. For example, é can be represented as a single precomposed character or as e followed by a combining accent. These forms may look the same but produce different UTF-8 bytes unless they're normalized to a common form.
Three Reasons Your Hex Output Doesn't Match
1. Different Character Encodings
Encoding determines how characters become bytes. UTF-8 is widely used on the web, but older applications and specialized systems may use other encodings. A character that occupies one byte in one encoding may require multiple bytes in another.
This difference becomes especially noticeable with accented letters, non-Latin scripts, symbols, and emoji. If two tools use different encodings, comparing their hexadecimal output without checking those settings can lead you down the wrong debugging path.
2. Hidden Characters That Sneak Into the Text
Not every character is visible. A string may contain a tab, a nonbreaking space, a carriage return, a line feed, or an invisible Unicode character. These can appear after copying text from a spreadsheet, document, website, or terminal.
For example, the word Hello encoded as UTF-8 produces 48 65 6C 6C 6F. Add a line feed at the end, and the bytes become:
48 65 6C 6C 6F 0A
That final 0A is the line-feed byte. The visible word hasn't changed, but the underlying data has. In a system that compares exact bytes, that single extra value can be enough to cause a mismatch.
3. Unicode Normalization and Different Text Representations
Unicode gives developers flexibility in representing certain characters. A character with an accent might be stored as one code point or as a base character followed by a combining mark. Both can render identically, but their encoded bytes differ.
This matters when comparing strings from databases, web forms, APIs, or applications that normalize text differently. If exact byte equality matters, check whether both systems apply the same Unicode normalization rules before converting the text.
Run a Small Experiment Before You Debug Anything
You don't need a complicated development environment to start investigating. Pick a few short test strings and compare their hexadecimal output.
Start with Hello. This gives you a simple baseline because its characters are represented consistently in UTF-8 and ASCII. Next, test café to see how a multibyte character changes the output. Finally, add a trailing space or line break and check whether the result gains extra bytes.
You can use the text to hex tool to inspect how your text is represented in hexadecimal. Run each test separately, keeping the original text unchanged except for the specific character or formatting difference you're investigating.
The trick is to change one variable at a time. If you change the encoding, remove a line break, and normalize Unicode simultaneously, you may fix the mismatch without discovering what caused it. A controlled test gives you a much clearer answer.
How to Find Where the Difference Starts
When two hexadecimal strings don't match, compare them from left to right. The first differing byte is a useful starting point, but it isn't automatically proof of corruption.
If the difference appears near the beginning, check for a byte-order mark, a different encoding, or an unexpected prefix. If the strings match until the final few bytes, inspect trailing whitespace, line endings, or extra data appended by the application. If the difference appears around an accented character or emoji, investigate the encoding and Unicode representation.
Also check whether both systems are converting the same thing. One tool may encode the raw text, while another may include a terminator, serialize the value into a structured format, or convert an entire file rather than just its visible contents. Those are different operations, even if the interface makes them look similar.
For automated workflows, compare the original character sequence, the encoding configuration, and the final byte sequence at each stage. This helps identify whether the difference originated during input, conversion, transmission, or storage.
When Should You Use a Text-to-Hex Converter?
A text-to-hex converter is useful when you need to inspect the byte representation of a string, investigate invisible characters, verify an encoding example, or compare data passed between systems. It turns otherwise hard-to-read byte values into a format that's easier to examine.
However, hexadecimal is a representation, not a universal explanation of what data means. A hex string alone doesn't tell you which encoding was used, whether the original text was normalized, or whether additional processing occurred. Those details must come from the context in which the bytes were created.
A Quick Checklist Before You Blame the Data
When the same text produces different hexadecimal output, work through these checks:
- Confirm the input: Make sure both systems received exactly the same characters.
- Check the encoding: Verify whether both use UTF-8 or another compatible encoding.
- Inspect invisible characters: Look for spaces, tabs, line endings, and unexpected Unicode characters.
- Check normalization: Determine whether Unicode normalization is applied consistently.
- Compare the first mismatch: Identify where the byte sequences begin to differ.
- Review the conversion process: Make sure both tools encode the same data without extra prefixes or suffixes.
The bottom line? Different hex output doesn't automatically mean your data is broken. Sometimes the difference comes from encoding; sometimes it's a hidden character; sometimes the two systems simply aren't processing the same byte sequence. Identify the first point of divergence, test one variable at a time, and you'll spend less time guessing—and more time fixing the actual problem.